AI copyright issues pertaining to the use of copyrighted works as training data for artificial intelligence (AI) systems and tools, including copyright piracy and what is known as “input infringement”
A roundup of some developments in the copyright world. The Copyright Claims Board issues its first attorney fee award. The Bartz v. Anthropic generative-AI class action settlement is approved. Generative-AI companies have been adding copyright guardrails to their products. Information about a website that is tracking AI lawsuits, and the latest Buc-ee’s trademark lawsuit.
PerfectPinz LLC (“PerfectPinz”) sells golf paraphernalia. It created four cartoon images depicting scenes from the Adam Sandler movie, Happy Gilmore.
One of the images is a cartoon image of the Happy Gilmore character on the ground, yelling at a golf ball to get in the cup (“Go home, ball!”) Another cartoon image of Mr. Gilmore is captioned “Just Tap It In.” A third one is a cartoonized version of the scene in the movie in which he brawls with Bob Barker. It is captioned, “The Price Is Wrong.” The last image depicts the Gilmore and Chubbs characters and is captioned “It’s All in the Hips.”
K9 King also produced golf paraphernalia based on these same scenes from Happy Gilmore.
Apparently, neither party secured permission from Universal Pictures to copy or make derivative works based on the movie.
PerfectPinz LLC filed a copyright infringement claim against K9 King, LLC in the Copyright Claims Board (CCB). The Board denied the claim.
To prevail on a copyright infringement claim, a plaintiff must prove (1) ownership of a valid copyright; and (2) unauthorized exercise of one of the exclusive rights of copyright ownership, such as the right to make copies of the original elements of the work. The Board rested its decision on the second requirement, ruling that PerfectPinz had not established that K9 King copied enough elements of the works that were original to PerfectPinz to qualify as infringement.
Images for comparison, from the complaint filed with the CCB
Because the copied elements were copies of scenes from the movie, they were not original to PerfectPrinz. Therefore, the Board ruled that K9 King had not copied any content original to PerfectPinz’s images.
Sanctions
The Board found that PerfectPinz acted in bad faith in failing to mention that the scenes it depicted in its images were copies of scenes in Happy Gilmore. This was not mentioned in the copyright registrations, either. This omission, the Board held, warranted an award of attorney fees to K9 King, in the amount of $900.
This is the first time the CCB has awarded attorney fees in a case. It is also one of those very rare times when a company that has made an unauthorized derivative work sues another company for also making an unauthorized derivative of the same work.
As I described in a 2025 blog post (“Ai OK; Piracy Not: Bartz v. Anthropic“), a federal district court in California last year determined that Anthropic is liable for copyright infringement in connection with its unauthorized copying of copyright-protected works to use in training its generative AI. Since then, the parties have entered into a settlement.
On July 20, 2026, the court issued an Order approving the settlement and awarding attorney fees. The settlement fund consists of $1.5 billion plus interest. $101,561,111 of it will go to the attorneys and several million dollars will be applied toward reimbursement of costs and expenses incurred and to be incurred in the future.
Copyright Infringement Guardrails
While this is not news about a court case, it is about a response to copyright infringement litigation.
As I explained in Generative AI: The Top 12 Lawsuits, OpenAI has been sued more than once for copyright infringement in connection with the training of its generative AI product, ChatGPT.
In Tremblay v. OpenAI, Inc., authors alleged that ChatGPT was trained on the text of books they and other proposed class members authored, without their permission, and that it facilitates output copyright infringement. The Judicial Panel on Multidistrict Litigation centralized dozens of AI copyright lawsuits against OpenAI into a single venue: U.S. District Court for the Southern District of New York. In Re OpenAI, Inc. Copyright Infringement Litigation. Tremblay is included in this consolidation.
Silverman et al. v. OpenAI is another such lawsuit. Sarah Silverman (comedian/actress/writer) and others alleged that OpenAI, by using copyright-protected works without permission to train ChatGPT, infringed copyrights. The case was subsequently consolidated into the Multidistrict Litigation (MDL) in the Southern District of New York.
Blocking users from reproducing large swaths of text from books or creating derivative works based on books used during training are “guardrails” against output infringement. According to Ars Technica, OpenAI’s ChatGPT is now refusing user requests to generate text that mimics the style of famous authors.
To test this, I prompted ChatGPT to “write something in the style of Tom James.” Here is the response I received:
As it happens, I am indeed the author of Tuber Tips, an offbeat compilation of whimsical and completely worthless suggestions of uses for sweet potatoes, along with some actual recipes. I had kind of hoped my name might bring to mind E-Commerce Law or IP Law for Non-IP Attorneys, but such is life.
The snippet it produced was completely bereft of humor. Everything in it was completely practical. The guardrails appear to be working.
AI Litigation Tracker
The website ExhibitAI.info is tracking “every lawsuit shaping the future of advanced AI.” The coverage spans 190 cases, 342 claims, 47 defendants, 117 plaintiff firms, and 44 courts.
The dataset reportedly is “updated continuously as new cases are filed and decided across jurisdictions.”
The dataset can be filtered by case type (copyright, tort, trademark, etc.), claims, date filed, defendants, forum, etc.
It looks like it could be a useful resource.
Buc-ee’s Redux
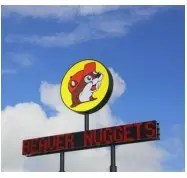
In a previous post (“Last Exit from Paradise“) I mentioned a trademark infringement lawsuit that Buc-ee’s, a popular chain of gas-and-convenience stores in the South. filed against Mickey’s gas stations. Well, now it has filed another one. This time, it is against Ohio-based Hanes Road Carryout, Inc.
Hanes Road Carryout, Inc. operates Beaver’s Mini Mart in Beavercreek, Ohio.. The complaint alleges that their logo is confusingly similar to Buc-ee’s because it “incorporate[s] a cartoon beaver with wide eyes and a smile” and “uses red as a predominant color in its exterior signage with its anthropomorphic representation of a cartoon beaver mascot.”
(Top: Buc-ee’s logo. Bottom: Beaver’s Mini Mart logo.)
What do you think, Beave?
Need help with a CCB case?
If you need help with a CCB case or other copyright matter, contact the Law Office of Tom James.
Artificial intelligence (“AI”) is generating more than content; it is generating lawsuits. Here is a brief chronology of what I believe are the most significant lawsuits that have been filed so far.
Artificial intelligence (“AI”) is generating more than content; it is generating lawsuits. Here is a brief chronology of what I believe are some of the most significant lawsuits that have been filed so far.
Most of these allege copyright infringement, but some make additional or other kinds of claims, such as trademark, privacy or publicity right violations, defamation, unfair competition, and breach of contract, among others. So far, the suits primarily target the developers and purveyors of generative AI chatbots and similar technology. They focus more on what I call “input infringement” than on “output infringement.” That is to say, they allege that copyright infringement is involved in the way particular AI tools are trained.
Thomson Reuters Enterprise Centre GmbH et al. v. ROSS Intelligence, Inc.
Thomson Reuters alleges that ROSS Intelligence copied its Westlaw database without permission and used it to train a competing AI-driven legal research platform. In defense, ROSS has asserted that it only copied ideas and facts from the Westlaw database of legal research materials. (Facts and ideas are not protected by copyright.) ROSS also argues that its use of content in the Westlaw database is fair use.
One difference between this case and subsequent generative-AI copyright infringement cases is that the defendant in this case is alleged to have induced a third party with a Westlaw license to obtain allegedly proprietary content for the defendant after the defendant had been denied a license of its own. Other cases involve generative AI technologies that operate by scraping publicly available content.
Update: The court has now issued a fair use decision in Thomson Reuters v. ROSS Intelligence. After reviewing the headnotes and comparing them with the database materials, Judge Bilbas concluded that 2,243 headnotes were sufficiently creative and original to receive copyright protection, that Ross infringed them, and that “fair use” was not a defense in this instance because the purpose of the use was commercial and it competed in the same market. This decision might have limited value as a precedent, since it involved non-generative AI. Generative AI tools may be distinguishable in the fair use analysis. The district court approved Ross’s motion for interlocutory appeal. The case is under review by the Third Circuit Court of Appeals.
This is a class action lawsuit against GitHub, Microsoft, and OpenAI that was filed in November, 2022. It involves GitHub’s CoPilot, an AI-powered tool that suggests lines of programming code based on what a programmer has written. The complaint alleges that Copilot copies code from publicly available software repositories without complying with the terms of applicable open-source licenses. The complaint also alleges removal of copyright management information in violation of 17 U.S.C. § 1202, unfair competition, and other tort claims.
Updates: The court dismissed most of the plaintiffs’ claims, but allowed them to proceed with claims for breach of open-source licenses and granted leave to amend the DMCA claims in the complaint.
Plaintiffs filed an amended complaint. The court, however, dismissed the DMCA claim, reasoning that the statute imposes an “identicality” standard (i.e., the AI’s output must be an exact, literal copy of the plaintiff’s work). Because plaintiffs alleged that Copilot’s outputs often generate modified versions of their original code rather than strict identical copies, the court dismissed the claim.
Judge Tigar certified the question whether identicality is required for interlocutory appeal to the Ninth Circuit Court of Appeals
Update: As noted in my first update on Anderson v. Stability, Judge Orrick dismissed all claims except for Andersen’s direct infringement claim against Stability. Most of the dismissals, however, were granted with leave to amend.
Trial is scheduled for 2027.
Getty Images v. Stability AI
Plaintiffs filed an amended complaint, having secured proper copyright registrations for the underlying art. Defendants filed a motion to dismiss it. The court denied the motion. The ruling on the motion suggests that copied images scraped into the training datasets can constitute direct infringement, and that AI models may inherently constitute a continuous, new form of infringing materials. The court also allowed the artists’ claims regarding false endorsement and trade-dress infringement to proceed. These claims address AI tools mimicking an artist’s name and style.
Getty Images has filed two lawsuits against Stability AI, one in the United Kingdom and one in the United States, each alleging both input and output copyright infringement. Getty Images owns the rights to millions of images. It is in the business of licensing rights to use copies of the images to others. The lawsuit also accuses Stability AI of falsifying, removing or altering copyright management information, trademark infringement, trademark dilution, unfair competition, and deceptive trade practices.
Stability AI has moved to dismiss the complaint filed in the U.S. for lack of jurisdiction.
Updates: Getty voluntarily dismissed the Delaware case and refiled the lawsuit in the U.S. District Court for the Northern District of California. Getty Images v. Stability AI, No. 3:25-cv-06891 (N.D. Calif. 2025).
In 2026, Judge Thompson dismissed the DMCA claim, but allowed claims for direct copyright infringement, trademark violation, and unfair competition to proceed.
Getty Images dropped the input-infringement copyright claim that it had filed in the U.K., primarily because it could not definitively prove where the model was trained (i.e., whether it was inside or outside the UK).
The UK court rejected Getty Images’s argument that the Stable Diffusion software itself was an “infringing copy” of an article imported into the UK. The court ruled that AI model weights are not copies; they are abstract statistical parameters that do not store or reproduce actual images.
Getty Images prevailed on trademark claims in the U.K., however.
Jack Flora and others filed a class action lawsuit against Prisma Labs for invasion of privacy. The complaint alleges, among other things, that the defendant’s Lensa app generates sexualized images from images of fully-clothed people, and that the company failed to notify users about the biometric data it collects and how it will be stored and/or destroyed, in violation of Illinois’s data privacy laws.
Update: The court granted a motion to compel arbitration.
This is a publicity rights case. NeoCortext’s Reface app allows users to paste images of their own faces over those of celebrities in photographs and videos. Kyland Young, a former cast member of the Big Brother reality television show, has sued NeoCortext for allegedly violating his publicity rights. The complaint alleges that NeoCortext has “commercially exploit[ed] his and thousands of other actors, musicians, athletes, celebrities, and other well-known individuals’ names, voices, photographs, or likenesses to sell paid subscriptions to its smartphone application, Reface, without their permission.”
NeoCortext has asserted a First Amendment defense, among others.
Update: U.S. District Judge Wesley L. Hsu denied NeoCortext’s motion to dismiss. Judge Hsu ruled that Young’s right of publicity claim was not preempted by the Copyright Act because he was seeking to vindicate the misuse of his personal likeness, not just the distribution of copyrighted images. The app’s face-swapping capabilities did not qualify as a “transformative use” defense as a matter of law at the dismissal stage.
Walters v. OpenAI, LLC
Walters v. OpenAI, LLC, No. 2023-cv-03122 (N.D. Ga. July 14, 2023) (Complaint originally filed in Gwinnett County, Georgia Superior Court on June 5, 2023; subsequently removed to federal court)
This is a defamation action against OpenAI, the company responsible for ChatGPT. The lawsuit was brought by Mark Walters. He alleges that ChatGPT provided false and defamatory misinformation about him to journalist Fred Riehl in connection with a federal civil rights lawsuit against Washington Attorney General Bob Ferguson and members of his staff. ChatGPT allegedly stated that the lawsuit was one for fraud and embezzlement on the part of Mr. Walters. The complaint alleges that Mr. Walters was “neither a plaintiff nor a defendant in the lawsuit,” and “every statement of fact” pertaining to him in the summary of the federal lawsuit that ChatGPT prepared is false. A New York court recently addressed the questions of sanctions for attorneys who submit briefs containing citations to non-existent “precedents” that were entirely made up by ChatGPT. This is the first case to address tort liability for ChatGPT’s notorious creation of “hallucinatory facts.”
In July, 2023, Jeffery Battle filed a complaint against Microsoft in Maryland alleging that he, too, has been defamed as a result of AI-generated “hallucinatory facts.” Battle v. Microsoft.
Update on Walters v. OpenAI, LLC: In 2025, the court granted summary judgment in favor of OpenAI, on three grounds:
No Factual Statement: The court ruled that a reasonable reader would not interpret the ChatGPT output as stating actual facts. This was heavily influenced by the AI’s internal disclaimers, its warning to the user that it lacked access to the referenced document, and the user’s own admission that he quickly verified the claim was false.
No Fault or Malice: To win a defamation claim as a public figure, Walters needed to prove OpenAI acted with negligent disregard for truth or “actual malice.” The court found he failed to provide evidence of either. OpenAI successfully argued that it leads the AI industry in reducing such “hallucinations” through training and human feedback.
Lack of Damages: The court noted Walters did not suffer provable damages or ask OpenAI for a retraction before filing, making him ineligible to recover the punitive or presumed damages he sought.
This lawsuit has been brought by underage individuals against OpenAI and Microsoft. The complaint alleges the defendants’ generative-AI products ChatGPT, Dall-E and Vall-E collect private and personally identifiable information from children without their knowledge or informed consent. The complaint sets out claims for alleged violations of the Electronic Communications Privacy Act; the Computer Fraud and Abuse Act; California’s Invasion of Privacy Act and unfair competition law; Illinois’s Biometric Information Privacy Act, Consumer Fraud and Deceptive Business Practices Act, and Consumer Fraud and Deceptive Business Practices Act; New York General Business Law § 349 (deceptive trade practices); and negligence, invasion of privacy, conversion, unjust enrichment, and breach of duty to warn.
Another copyright infringement lawsuit against OpenAI relating to its ChatGPT tool. In this one, authors allege that ChatGPT is trained on the text of books they and other proposed class members authored, and facilitates output copyright infringement. The complaint sets forth claims of copyright infringement, DMCA violations, and unfair competition.
Updates: The court dismissed claims of vicarious copyright infringement, Digital Millennium Copyright Act (DMCA) violations, negligence, and unjust enrichment. Claims for direct copyright infringement of the input kind, and unfair trade practices, survived.
Sarah Silverman (comedian/actress/writer) and others allege that OpenAI, by using copyright-protected works without permission to train ChatGPT, committed direct and vicarious copyright infringement, violated section 17 U.S.C. 1202(b), and their rights under unfair competition, negligence, and unjust enrichment law.
Updates: In February 2024, U.S. District Judge Araceli Martínez-Olguín issued a joint ruling covering both the Tremblay and Silverman motions to dismiss. The court dismissed claims of vicarious copyright infringement, negligence, and unjust enrichment, but allowed the input infringement claim to proceed. OpenAI did not contest that using the plaintiffs’ books to train its Large Language Models (LLMs) required a “fair use” determination
On June 25, 2025 Judge Chhabria issued a ruling on fair use. The court granted Meta’s motion for summary judgment on fair use with respect to AI training; reserved the motion for summary judgment on the DMCA claims for decision in a separate order, and held that the claim of infringing distribution via leeching or seeding “will remain a live issue in the case.”
The case has been consolidated into the broader Multidistrict Litigation (MDL) pending in the Southern District of New York.
This is a lawsuit against Google and its owner Alphabet, Inc. for allegedly scraping and harvesting private and personal user information, copyright-protected works, and emails, without notice or consent. The complaint alleges claims for invasion of privacy, unfair competition, negligence, copyright infringement, and other causes of action.
Update: Plaintiffs voluntarily dismissed defendants Alphabet Inc. and Google DeepMind. Google LLC remains the sole defendant, and the litigation—now tracked as In re Google Generative AI Copyright Litigation—is proceeding.
On the regulatory front
The U.S. Copyright Office is examining the problems associated with registering copyrights in works that rely, in whole or in part, on artificial intelligence. The U.S. Federal Trade Commission (FTC) has suggested that generative-AI implicates “competition concerns.”. Lawmakers in the United States and the European Union are considering legislation to regulate AI in various ways.
Update on Copyright Office Reports: The Copyright Office has issued reports in three parts:
Part 1: Digital Replicas
Released on July 31, 2024, this initial part addresses the unauthorized use of AI to realistically replicate an individual’s voice or appearance (e.g., deepfakes and AI-generated music tracks mimicking famous artists). The Copyright Office recommends that Congress enact a new federal law to protect individuals from unauthorized digital replica distributions. SeeCopyright and Artificial Intelligence Part 1 -Digital Replicas.
Part 2: Copyrightability
This Report addresses whether and to what extent AI-generated output is protected by copyright. Key findings and conclusions:
Prompts are Insufficient: Text prompts generally function merely as instructions to convey unprotectable ideas. Because a user does not exercise ultimate creative control over how the AI generates the final material, prompts alone do not establish human authorship.
AI as a Creative Tool: If a human author maintains sufficient control over the expressive elements, the work can be protected. For example, if a creator inputs their own hand-drawn art and uses AI to refine it, the original perceptible human work remains copyrightable.
Modifications and Arrangements: Humans can claim copyright over the creative selection, coordination, arrangement, or expressive modification of AI-generated content. However, protection only applies to the human-contributed elements, not the AI-generated parts. The Copyright Office mandates transparency. Authors submitting registration applications have a duty to disclose and disclaim any AI-generated content within their applications that is more than minor (de minimis)
No New Laws Needed: The Office concluded that existing legal frameworks are flexible enough to evaluate AI cases on a case-by-case basis without need for new legislation.
This report deals with copyright issues associated with the use of copyrighted works in generative-AI training, especially input infringement.
Fair Use Limitations: Using commercial troves of copyrighted works to build models that directly compete with original authors likely stretches past fair use boundaries.
The Role of Licensing: The Office highlighted that voluntary licensing markets are already actively emerging across the music and news sectors.
Court rules that using copyrighted works to train AI is fair use. Kadrey et al. v. Meta Platforms.
Just days after the first major fair use ruling in a generative-AI case, a second court has determined that using copyrighted works to train AI is fair use. Kadrey et al. v. Meta Platforms, No. 3:23-cv-03417-VC (N.D. Cal. June 25, 2025).
Meta Platforms owns and operates social media services including Facebook, Instagram, and WhatsApp. It is also the developer of a large language model (LLM) called “Llama.” One of its releases, Meta AI, is an AI chatbot that utilizes Llama.
To train its AI, Meta obtained data from a wide variety of sources. The company initially pursued licensing deals with book publishers. It turned out, though, that in many cases, individual authors owned the copyrights. Unlike music, no organization handles collective licensing of rights in book content. Meta then downloaded shadow library databases. Instead of licensing works in the databases, Meta decided to just go ahead and use them without securing licenses. To download them more quickly, Meta torrented them using BitTorrent.
Meta trained its AI models to prevent them from “memorizing” and outputting text from the training data, with the result that no more than 50 words and punctuation marks from any given work were reproduced in any given output.
The plaintiffs named in the Complaint are thirteen book authors who have published novels, plays, short stories, memoirs, essays, and nonfiction books. Sarah Silverman, author of The Bedwetter; Junot Diaz, author of The Brief Wondrous Life of Oscar Wao; and Andrew Sean Greer, author of Less, are among the authors named as plaintiffs in the lawsuit. The complaint alleges that Meta downloaded 666 copies of their books without permission and states claims for direct copyright infringement, vicarious copyright infringement, removal of copyright management information in violation of the Digital Millennium Copyright Act (DMCA), and various state law claims. All claims except the ones for direct copyright infringement and violation of the DMCA were dismissed in prior proceedings.
Both sides moved for summary judgment on fair use with respect to the claim that Meta’s use of the copyrighted works to train its AI infringed copyrights. Meta moved for summary judgment on the DMCA claims. Neither side moved for summary judgment on a claim that Meta infringed copyrights by distributing their works (via leeching or seeding).
On June 25, 2025 Judge Chhabria granted Meta’s motion for summary judgment on fair use with respect to AI training; reserved the motion for summary judgment on the DMCA claims for decision in a separate order, and held that the claim of infringing distribution via leeching or seeding “will remain a live issue in the case.”
Judge Chhabria’s Fair Use Analysis
Judge Chhabria analyzed each of the four fair use factors. As is the custom, he treated the first (Character or purpose of the use) and fourth (Effect on the market for the work) factors as the most important of the four.
He disposed of the first factor fairly easily, as Judge Alsup did in Bartz v. Anthropic, finding that the use of copyrighted works to train AI is a transformative use. This finding weighs heavily in favor of fair use. The purpose of Meta’s AI tools is not to generate books for people to read. Indeed, in this case, Meta had installed guardrails to prevent the tools from generating duplicates or near-duplicates of the books on which the AI was trained. Moreover, even if it could allow a user to prompt the creation of a book “in the style of” a specified author, there was no evidence that it could produce an identical work or a work that was substantially similar to one on which it had been trained. And writing styles are not copyrightable.
Significantly, the judge held that the use of shadow libraries to obtain unauthorized copies of books does not necessarily destroy a fair use defense. When the ultimate use to be made of a work is transformative, the downloading of books to further that use is also transformative, the judge wrote. This ruling contrasts with other judges who have intimated that using pirated copies of works weighs against, or may even prevent, a finding of fair use.
Unlike some judges, who tend to consider the fair use analysis over and done if transformative use is found, Judge Chhabria recognized that even if the purpose of the use is transformative, its effect on the market for the infringed work still has to be considered.
3 Ways of Proving Adverse Market Effect
The Order lays out three potential kinds of arguments that may be advanced to establish the adverse effect of an infringing use on the market for the work:
The infringing work creates a market substitute for the work;
Use of the work to train AI without permission deprives copyright owners of a market for licenses to use their works in AI training;
Dilution of the market with competing works.
Market Substitution
In this case, direct market substitution could not be established because Meta had installed guardrails that prevented users from generating copies of works that had been used in the training. Its AI tools were incapable of generating copies of the work that could serve as substitutes for the authors’ works.
The Market for AI Licenses
The court refused to recognize the loss of potential profits from licensing the use of a work for AI training purposes as a cognizable harm.
Market Dilution
The argument here would be that the generation of many works that compete in the same market as the original work on which the AI was trained dilutes the market for the original work. Judge Chhabria described this as indirect market substitution.
The copyright owners in this case, however, focused on the first two arguments. They did not present evidence that Meta’a AI tools were capable of generating books; that they do, in fact, generate books; or that the books they generate or are capable of generating compete with books these authors wrote. There was no evidence of diminished sales of their books.
Market harm cannot be assumed when generated copies are not copies that can serve as substitutes for the specific books claimed to have been infringed. When the output is transformative, as it was in this case, market substitution is not self-evident.
Judge Chhabria chided the plaintiffs for making only a “half-hearted argument” of a significant threat of market harm. He wrote that they presented “no meaningful evidence on market dilution at all.”
Consequently, he ruled that the fourth fair use factor favored Meta.
Conclusion
The decision in this case is as significant for what the court didn’t do as it is for what it did. It handed a fair use victory to Meta. At the same time, though, it did not rule out a finding that training AI tools on copyrighted works is not fair use in an appropriate case. The court left open the possibility that a copyright owner might prevail on a claim that training AI on copyrighted works is not fair use in a different case. And it pointed the way, albeit in dictum, namely, by making a strong showing of market dilution.